
Three weeks ago, the “godmother of AI” published a taxonomy that reads, if you squint, like a buyer’s guide for a market nobody has named a winner in yet. Here is what it actually tells founders about where to point capital.
Fei-Fei Li and her World Labs team put out an essay on June 3 with a deceptively academic title: a functional taxonomy of world models. On the surface it is a tidy bit of definitional housekeeping, splitting one overloaded buzzword into three. Underneath, it is a positioning document for a company that just raised over a billion dollars, and a quiet argument about which slice of the AI stack is going to matter most after the language model gold rush cools off.
If you build, invest, or just try to read the AI tea leaves for a living, the three-way split is worth your time. Not because the categories are clever, but because they map cleanly onto three completely different business realities: one mature and commoditizing, one barely real, and one that a $50 trillion company is betting the next decade on.
World Model: A world model is an AI system that learns the structure of physical space and time rather than the structure of text. Where a language model predicts the next word, a world model predicts how a scene looks from a new angle, how an object behaves when pushed, or what an agent should do next. The term is borrowed from decades-old reinforcement learning theory, where an agent takes actions, the world changes state, and the agent receives partial observations in return. Li’s argument is that the systems people call “world models” today are each just one slice of that loop.
The three jobs, and why the distinction is a money question
Li’s framework breaks the loop into three outputs. A renderer produces pixels. A simulator produces state. A planner produces actions. That sounds like an engineering distinction. It is really a market-structure distinction, because each one has a different customer, a different moat, and a different distance from revenue.
| World model type | What it outputs | Who pays for it | Commercial reality (mid-2026) |
|---|---|---|---|
| Renderer | Pixels for human eyes | Consumers, marketers, creative tools | Mature and crowded. Beautiful output, thin defensibility. |
| Simulator | Physically faithful state | Roboticists, automakers, architects, factories | The hard one. Scarce data, brutal compute, highest leverage. |
| Planner | Actions an agent should take | Robotics and autonomous systems builders | Most funded, least proven. Impressive demos, no reliable deployment. |
The trap is treating these as a maturity ladder where everyone graduates from rendering to planning. They are not stages. They are separate businesses with separate economics, and the smartest framing in Li’s essay is that the same underlying knowledge of geometry, physics, and dynamics sits beneath all three. Whoever owns that substrate can project it into any of the three outputs. Whoever owns only one output is renting.
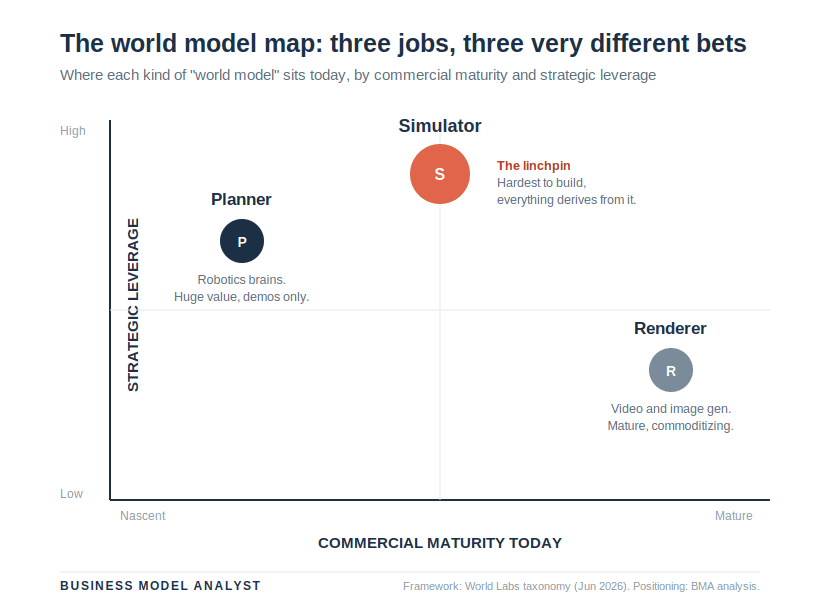
Here is the same idea as a positioning map. The vertical axis is strategic leverage, meaning how much the rest of the stack depends on you. The horizontal axis is how commercially mature each category is today.
The renderer: real revenue, shrinking moat
The renderer is the part of the world model market that already works. Text-to-video and text-to-image products are shipping to hundreds of millions of users. Google’s interactive Genie 3, its Nano Banana image model, and World Labs’ own real-time systems all live here. The technology is real and the markets are real.
The catch is the ceiling. Renderers optimize for looking right, not being right. A drone shot of a city can look flawless from above and fall apart the moment you try to drive a simulated car through the streets below. That is fine for a movie and useless for training a robot. And because the output is “a pretty image,” the category is commoditizing fast, in exactly the pattern we traced in our breakdown of why AI margins are migrating down the stack. When the product is interchangeable, price is the first thing customers squeeze. Renderers are the part of this market most exposed to that squeeze.
The simulator: the linchpin nobody is staring at
This is the bet. Li’s whole essay is built to argue that the simulator, the least glamorous of the three, is the most consequential, and that the rest of the industry is underbuilding it.
The logic is structural. If language abstracts the world and pixels project it, then geometry, physics, and dynamics are the world itself. A model that masters simulation can derive a pretty picture for a human or an action prediction for a robot. A model that only renders, or only plans, cannot do the reverse. Master the middle and you can serve both ends.
The capital agrees. World Labs has now raised about $1.23 billion total. In February it closed a $1 billion round anchored by a $200 million check from design-software giant Autodesk, its largest startup investment ever, alongside NVIDIA, AMD, Andreessen Horowitz, Emerson Collective, Fidelity, and Sea. Reporting pegged the valuation talks near $5 billion, a fivefold jump in roughly fifteen months. Its first product, Marble, turns text, images, or a rough 3D sketch into an explorable world, and crucially exports both Gaussian splats for viewing and collision meshes a physics engine can compute on. One model, two consumers. That is the simulator thesis made into a product.
And World Labs is not the scary competitor here. NVIDIA is. Its Omniverse and Isaac simulation stack already frames physical AI as a $50 trillion manufacturing and logistics opportunity, by the company’s own (forward-looking, take-it-with-salt) estimate. ABB, FANUC, KUKA, and Yaskawa, with a combined install base north of two million robots, are training fleets inside NVIDIA’s physically accurate digital twins before a single machine touches a factory floor. This is the same flywheel we mapped in the NVIDIA business model breakdown: sell the compute, own the simulation layer that runs on it, and rent the picks and shovels to everyone racing for the gold.
The honest counterweight: the simulator is hard for real reasons, not marketing ones. Three-dimensional data with proper geometry and physics is orders of magnitude scarcer than the internet video renderers train on. AI-generated geometry can look correct while hiding self-intersections or wrong scale that produce nonsense physics. And multi-physics simulation, where rigid bodies, fluids, and cloth all interact at once, remains brutally expensive. The leverage is highest here precisely because the problem is hardest.
The planner: the most funded, the least real
The planner outputs actions. Given a goal and an observation, it decides what a robot should do next. It is the inverse of the renderer, and it is the category venture capital is most in love with right now.
It is also the one demanding the most skepticism. Li’s own essay is unusually candid about this: nearly every impressive robotics demo of the last two years has been confined to heavily constrained lab setups, with narrow object sets and short task horizons, and none have been validated at the complexity, variability, or duration that real deployment demands. The gap between a great demo reel and a robot that reliably works in a warehouse, a kitchen, or an operating room is still vast.
That has not slowed the money. A wave of well-funded entrants, from Figure to Skild AI to the humanoid programs at Tesla and Boston Dynamics, are racing to ship general-purpose planning systems, while the infrastructure players position planning on top of broader simulation stacks. The strategic prize is obvious. A robot that can plan is a robot that can work. The operator’s question is whether you are buying a working product or a research bet with a product’s price tag.
What this actually means for operators
Strip away the taxonomy and three practical lessons fall out.
| If you are… | The lesson from the map |
|---|---|
| Building on world models | Match the category to the job. A renderer for marketing assets, a simulator for anything safety- or physics-critical, and treat planner products as pilots, not infrastructure, until deployment data exists. |
| Investing in the space | Maturity and defensibility are inversely correlated here. The mature category (rendering) is the easiest to commoditize. The defensible bet (simulation) is the hardest to build and the slowest to pay off. |
| Watching the AI capex story | World models are another reason the AI build-out keeps swallowing scarce compute. Simulation is even more compute-hungry than language, and the same chips are involved. |
The deeper signal is convergence. Li argues the three categories are starting to collapse into one, because the knowledge needed to render a cup, simulate it being pushed, and plan a hand to pick it up is largely the same knowledge. The endgame she sketches is a single foundation model that switches output modes on demand. If that bet is right, the winner will not be whoever ships the prettiest video or the flashiest robot demo. It will be whoever owns the physics underneath, and can rent it out in three directions at once.
The Business Model Analyst Take
Read this taxonomy as positioning, because that is what it is. A company that just raised over a billion dollars to build simulators published an essay arguing that simulators are the most important and most underbuilt category in AI. Of course it did. The argument is still largely correct, which is what makes it effective.
For founders, the useful takeaway is not the three-letter framework. It is the inverse relationship between how mature a category looks and how defensible it actually is. Rendering is where the revenue is today and where the margin gets competed away tomorrow. Planning is where the headlines are and where the disappointment will be when the demos meet a real warehouse. Simulation is the unglamorous middle that everything else has to route through, which is exactly why NVIDIA and Fei-Fei Li are both planting flags there. The boring layer is usually where the durable money lives. The trick, as always, is having the patience and the balance sheet to wait for the boring layer to pay.
Frequently Asked Questions
What is a world model in AI?
A world model is an AI system that learns the structure of physical space and time rather than the statistical structure of text. Instead of predicting the next word, it predicts how a scene looks from a new angle, how objects behave under force, or what action an agent should take next. The term comes from reinforcement learning, where an agent acts, the world changes state, and the agent receives partial observations.
What are the three types of world models?
Per Fei-Fei Li’s World Labs taxonomy, the three are renderers (which output pixels for human eyes and are judged on visual fidelity), simulators (which output physically faithful state that programs can compute on), and planners (which output the actions an agent should take). Each has a different customer and a different commercial maturity.
Why does World Labs say the simulator is the most important world model?
Because it sits beneath the other two. A model that can simulate the world accurately can derive both a rendered image for humans and an action prediction for robots. A renderer or planner alone cannot reverse that. World Labs argues the rest of the industry is underbuilding simulation even though it carries the most strategic leverage.
How much has World Labs raised?
World Labs has raised roughly $1.23 billion in total. Its February 2026 round of about $1 billion was anchored by a $200 million investment from Autodesk, with NVIDIA, AMD, Andreessen Horowitz, Emerson Collective, Fidelity, and Sea also participating. Reports placed the valuation near $5 billion.
Are AI-powered robots ready for real-world deployment?
Mostly not yet. Li’s own essay notes that nearly all impressive robotics demos to date have been confined to constrained lab settings with narrow tasks and short time horizons, and none have been validated at the complexity and duration real deployment requires. The funding is large, but reliable general-purpose deployment remains unproven.