
Reddit, USA Today, and the Economist are weighing whether to block the crawler that built them, as AI answers gut the traffic-for-content deal that funded the open web.
Major publishers including Reddit, USA Today, and Politico are weighing whether to block Google’s crawler as AI-generated search answers collapse their traffic. The old arrangement traded content for clicks at roughly five pages crawled per visitor sent back. AI crawlers now take hundreds or thousands of pages per referral, breaking the economics that funded ad-supported media.
For twenty years the open web ran on a simple handshake. Google crawled your pages, and in exchange it sent you readers you could turn into ad revenue. That handshake is coming apart, and the publishers who built entire businesses on it are now asking whether it is worth keeping Google’s hand at all.
What Happened
Reddit, the discussion platform that powers a large share of Google’s search results, has internally discussed shutting off Google’s access to its content for AI use, according to reporting in The Wall Street Journal. It is not alone. USA Today, Politico, the Economist, People Inc., and Reuters are all reassessing whether, and how, to keep working with the search engine that used to be their biggest source of visitors.
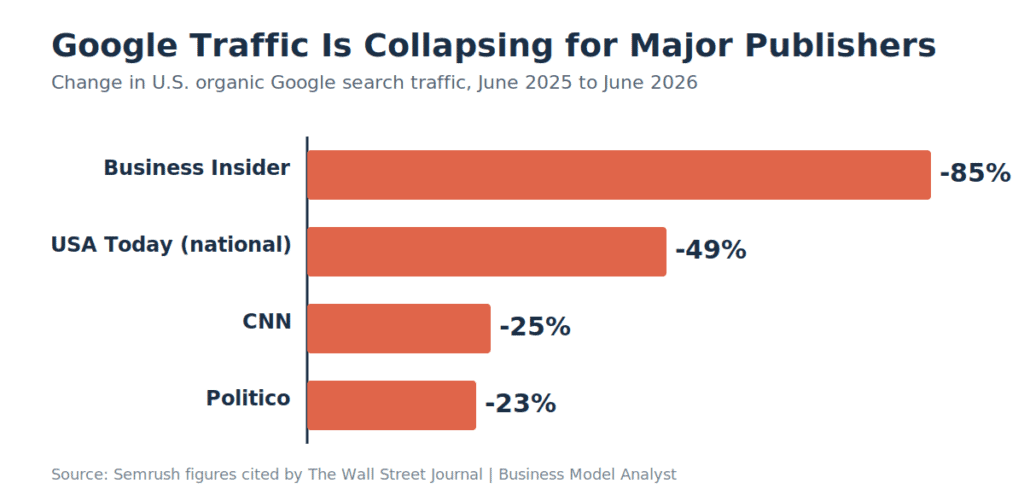
The frustration is about money, and the money is disappearing fast. Between June 2025 and June 2026, organic Google search traffic from U.S. users fell 23% for Politico, about 25% for CNN, nearly half for USA Today’s national paper, and more than 85% for Business Insider, according to figures cited by the Journal from search-measurement firm Semrush. The context underneath those numbers is a structural first: automated bots now account for 57.5% of all web traffic, per Cloudflare data published in June 2026. The human audience publishers actually monetize is now the minority visitor.
USA Today is willing to turn Google’s crawler off entirely if the decline continues, which would pull its content out of Google’s AI summaries and its blue-link search results at the same time. “It’s time to take a stand and say enough is enough,” the company’s chief executive Mike Reed told the Journal. People Inc.’s chief executive Neil Vogel was blunter, saying blocking the bots entirely is “100% on the table.”
The Backstory
The deal that built the modern web was crawl-for-clicks. Google indexes your content, ranks it, and sends referral traffic. You turn that traffic into ad impressions. Nobody signed a contract, but there was an implicit price: Google’s own crawler has historically sent a visitor for roughly every five pages it indexes. That was the exchange rate, and for two decades it worked well enough that an entire industry of ad-supported publishers organized itself around it. (For how that advertising machine actually monetizes attention, see our breakdown of the Google business model.)
AI broke the exchange rate in two directions at once.
First, the AI crawlers that harvest content for training and answers give almost nothing back. Where Googlebot returns a visitor for every five pages or so, the large AI crawlers take hundreds, and in some cases many thousands, of pages for every referral they send. The content flows out; the traffic does not flow back.
Second, and more damaging, Google turned its own search into an answer engine. AI Overviews now resolve the query on the results page, so the user never clicks through. Fewer than a third of Google searches ended in a click to any website in 2026, according to SparkToro. When an AI Overview appears, click-through to organic results falls by nearly half, a Pew Research study of roughly 68,000 queries found. The traffic is not being stolen by chatbots. It is evaporating inside Google’s own results.
Here is the trap that makes this so hard to escape: publishers can switch off crawling specifically for AI-model training, but to appear in either AI answers or ordinary blue-link results they generally have to let Googlebot crawl for both. The access is bundled. That bundle is the leverage Google holds.
The Plan
Publishers are spread across a spectrum of responses, sorted almost entirely by how much leverage they have.
At one end is blocking. USA Today and People Inc. are openly considering turning the crawler off. Politico staff have floated a softer version: a registration wall that forces humans to log in, keeping content out of reach of free-riding bots. Reuters is weighing a block on its consumer-facing news product while protecting its business-to-business revenue.
In the middle is renegotiation. Reddit struck a deal in 2024 worth about $60 million a year to let Google train models on its content, and the two are now in renewal talks with the value of that trade very much in question. Google, for its part, has launched a program paying more than 200 publishers for content access, and now lets users pick preferred news sources to personalize search results. (Reddit’s advertising-and-data model, and why its human discussion is worth paying for, is covered in our Reddit business model analysis.)
At the far end is litigation and regulation. Penske Media, owner of Variety and Rolling Stone, sued Google in September on antitrust grounds over its AI summaries. USA Today has a separate ad-tech monopoly suit pending. And a U.K. regulator has ruled that publishers can opt out of AI features without losing their place in traditional search, a decision Google says it will honor, starting with a U.K. test before any global rollout. The Economist has been actively debating whether to use that off-ramp, though exiting Google entirely is not on its table.
Then there is the most forward-looking response of all, which is to stop fighting the bots and start feeding them deliberately. Time is building text-based ads that human readers never see but AI crawlers might, hoping that Google’s AI Overviews and other chatbots surface that brand information when answering user questions. “There are now two audiences,” Time’s chief operating officer Mark Howard told the Journal, describing a strategy of serving humans directly while treating bots as a secondary audience worth reaching.
The Business Model Angle
Strip away the outrage and the lawsuits, and this is a repricing story.
The ad-supported content model was never really content sold to readers. It was content sold to Google, which rented you the readers. Traffic was the product. The ad impression was the invoice. What AI did was decouple the content from the traffic, which is the same as decoupling the product from the invoice. Google can now extract the value of your content, answer the user, and keep the visit. The supplier just watched its buyer figure out how to stop paying.
That reframing explains why the responses split so cleanly by leverage. Ask a simple question: who can actually afford to cut Google off? Only publishers with something Google cannot easily get somewhere else. Reddit can, because its real-time human discussion is genuinely scarce, which is exactly why Google paid for it. The Economist can lean on subscriptions. Reuters and Politico can fall back on business-to-business revenue that never depended on consumer clicks. For a pure-play SEO publisher whose entire income is display advertising against Google traffic, blocking the crawler is not a stand. It is a shutdown.
So the useful question is not whether to fight Google. It is what you own that does not depend on a click. There are only two durable answers. One is to become the cited source inside the AI answer, since a citation still carries brand value even when it does not carry a visitor, which is the whole logic behind generative and answer-engine optimization. The other is to diversify revenue off ad-dependent traffic entirely. People Inc. is the working template here: Google fell from more than half of its traffic two years ago to just 25% in the first quarter of this year, and the company grew revenue anyway through events, social referrals, and expanded apps.
Google is not a passive winner in this. It needs a living open web to keep its answers accurate and fresh, which is why it is paying publishers and surfacing preferred sources rather than simply strip-mining everyone. The company that spent twenty years disintermediating publishers now has an interest in keeping enough of them alive to feed the machine. Whether the payments come close to replacing the lost click economics is the open question, and the emerging signs in the traffic data suggest they do not. The pressure on Google’s own funnel is now prominent enough that it shows up in our Google SWOT analysis as a structural weakness, not a footnote.
The Risk
The biggest risk sits with the publishers themselves, because blocking Google is close to a one-way door. Turn the crawler off and you disappear from AI answers and blue links together. The Economist’s own framing captures the trap precisely: traffic can be choppy and declining, but traffic is still traffic, and walking away from it without a replacement revenue engine is a decision most publishers cannot survive.
There is also a collective-action problem. No single publisher blocking Google moves the needle, because Google has millions of substitute sources ready to fill the gap. Only coordinated action or regulation actually shifts the balance of power, and coordination among competitors invites its own antitrust scrutiny. That leaves individual publishers stuck negotiating from weakness against a counterparty that can afford to lose any one of them.
Google carries real risk too, though it is slower-moving. If enough high-quality publishers wall themselves off or go out of business, the quality of the answers degrades, because an answer engine is only as good as the sources it can reach. Layer on the antitrust suits over ad tech and AI summaries, plus regulators in the U.K. and EU already forcing AI features to be unbundled from search, and the leverage that looks total today is more contested than it appears.
The deepest risk is to the open web itself. If the crawl-for-clicks trade dies and nothing of equivalent value replaces it, the basic incentive to publish free, ad-supported content weakens for everyone. As one media consultant put it to the Journal, this is “existential for some categories of publishers.” The web that Google indexes was built by the promise of traffic. Remove the traffic, and you remove the reason it gets built.
Quick Questions
Can publishers block Google’s AI features without losing normal search traffic? Generally no. Googlebot’s crawling is bundled, so appearing in AI answers and blue-link results usually requires allowing both. The one exception is where regulators force an off-ramp, as a U.K. authority recently did.
How much traffic are publishers actually losing? Year over year through June 2026, U.S. organic Google traffic fell about 23% for Politico, roughly 25% for CNN, nearly half for USA Today’s national paper, and more than 85% for Business Insider, per Semrush figures cited by the Journal.
Do AI chatbots send publishers meaningful traffic yet? Not really. All AI chatbots combined sent a fraction of a percent of search referrals in 2026, while Google still sends the overwhelming majority. The traffic loss comes from Google’s own zero-click AI answers, not from chatbot competition.
Why is Reddit at the center of this? Its human discussion powers a large share of Google results and is valuable AI training material, which is why Google paid roughly $60 million a year for access. That makes Reddit one of the few publishers with real leverage to renegotiate or walk.
What is the realistic path forward for publishers? Diversify revenue away from ad-supported search traffic through events, subscriptions, apps, and licensing, while optimizing to be cited inside AI answers so the brand still travels even when the click does not.
The Business Model Analyst Take
The “cut Google off” headline is two different things at once. For the handful of publishers with scarce content or direct revenue, it is a negotiating posture. For everyone else, it is a suicide note. Treating those as the same story is the mistake most coverage will make.
The real signal is quieter and more important: the ad-supported content model is being repriced, not killed, and the repricing rewards whoever owns proprietary data, a direct audience relationship, or diversified revenue. If your business is “rank on Google and run display ads,” you are not a media company. You are a Google traffic reseller, and your supplier just cut your margin without asking. That is not a moral failing on Google’s part. It is what a dominant platform does when technology lets it capture more of the value it used to share.
The publishers who come out of this intact will stop asking how to get their clicks back and start asking what they own that a click cannot be taken away from. Community, first-party data, paid products, a brand people seek out by name. Traffic becomes one channel among several instead of the whole business. Everyone still treating Google referrals as oxygen is going to spend the next two years discovering how thin the air has gotten, and the ones who diversified early are going to look a lot smarter than they did when the traffic was still free.
Based on reporting by Alexandra Bruell for The Wall Street Journal, with search-traffic data from Semrush and additional figures from Cloudflare, SparkToro, and Pew Research.