
In July 2026, a New York startup called Pangram raised $9 million to catch AI writing. The round was led by Menlo Ventures, and it landed alongside two product launches: a new text detector the company says is over 99% accurate, and an image detector in research preview. The pitch is simple and, on the surface, compelling. As machine-generated content floods the internet, someone will pay to know what is real.
That thesis has now attracted real venture money across a whole category. GPTZero has raised $13.5 million. Copyleaks has raised roughly $7 million and cracked the Inc. 5000. Originality.ai built a profitable business aimed squarely at SEO teams. So the demand looks real. The harder question, the one that actually matters if you are trying to understand this market, is whether detection is a durable business or a bridge business. The evidence points to the second answer.
Here is how AI detectors make money, and why the model has a structural crack running straight through the middle of it.
What is an AI content detector? An AI content detector is software that estimates the probability that a piece of text or an image was generated by a large language model rather than a human. Most text detectors do not read metadata or watermarks. They learn the statistical fingerprints of machine writing, things like low perplexity and predictable word choice, and score new text against those patterns. The output is a probability, not a fact, which is the root of everything that follows.
The revenue model: consumer is the ad, enterprise is the business
Detectors sell in three layers, and only two of them make real money.
The first layer is the consumer subscription. Pangram charges $20 per month for web access plus a Chrome extension that labels posts in real time on X, LinkedIn, Substack, Reddit, and Medium, complete with a “feed health score” telling you how much of your timeline is machine-made. This tier is cheap, visible, and viral. It is also low-margin noise. Individual sleuths churn fast and pay little. Think of the consumer product as marketing that happens to charge rent, not as the business itself.
The second layer, the subscription model applied to institutions, is where the money actually lives. Detectors sell API access to organizations that need to screen text at volume: universities, publishers, recruiters, and platforms. This is Pangram’s real book of business, and it is why the Substack integration matters more than the Chrome extension. When Substack wired Pangram into its platform to flag which newsletter authors write with AI, that was not a consumer sale. That was a platform outsourcing a judgment call to a vendor, at scale, on recurring terms.
The third layer is bundling, and GPTZero is the case study. Rather than sell detection alone, GPTZero packages plagiarism checking, grading assistance, and authorship verification into one subscription. That lifts revenue per customer and creates stickiness: a school that adopts the detector discovers it likes the grading tools and stops shopping around. GPTZero reportedly reached profitability inside 18 months and has scanned more than 600 million documents, which becomes its own data moat.
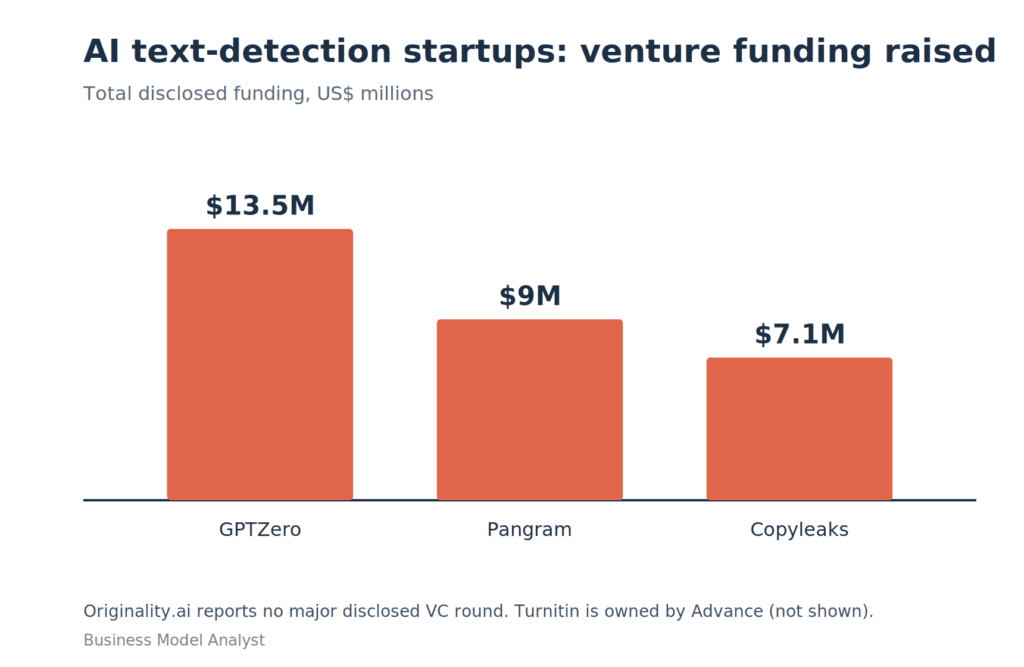
Put the players side by side and a pattern emerges. The winners are not the ones with the best detector. They are the ones who attached detection to a workflow a customer was already paying for.
Notice the market has already split by buyer. Originality.ai openly states it is built for publishers and content marketers, not students, and will not defend its accuracy for academic use. That is not a footnote. It is a tell that the “detect AI” product means completely different things to a marketer protecting ad revenue and a professor deciding whether to fail a student. One is a business tool. The other is an accusation. The same probability score cannot honestly serve both.
The information gain: the product is probabilistic, but it is sold as proof
Every detector markets a single number: accuracy. Pangram says over 99%. Turnitin has claimed a false-positive rate under 1%. These numbers are technically defensible and strategically misleading, because the business breaks not on average accuracy but on what happens at the edges and at scale.
Start with the company that knew the most and quit anyway. OpenAI built its own AI-text classifier, then shut it down in July 2023, stating plainly that it was retiring the tool over its low rate of accuracy. By OpenAI’s own published numbers, the classifier correctly caught just 26% of AI-written text while wrongly flagging 9% of human text as machine-made.
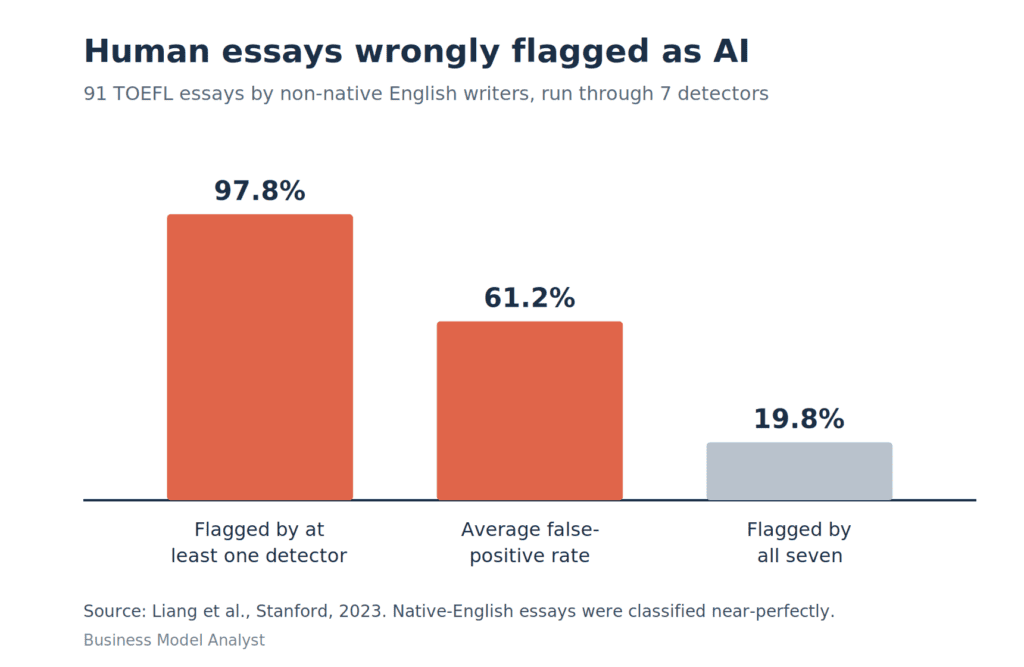
The firm with arguably the deepest understanding of how these models generate text could not build a detector it was willing to stand behind. That is the single most important data point in this entire category, and most coverage of detection funding rounds skips right past it.
Now the false-positive problem, which is where the model quietly rots. Pangram says roughly 1 in 10,000 human documents gets mislabeled as AI. That sounds like precision. Run it at internet scale and it becomes a firehose of false accusations. A platform screening ten million posts is wrongly flagging a thousand real humans, every pass. When the output is a public “AI” label or a disciplinary trigger, a rare error rate is not a rounding detail. It is a steady stream of people wrongly accused, and the cost of each error lands on a person, not on the vendor.
The bias problem makes it worse and more specific. In a widely cited Stanford study, researchers ran 91 essays written by non-native English speakers through seven leading detectors. The tools falsely flagged an average of 61% of these human-written essays as AI. At least one detector flagged 89 of the 91. The same tools were near-perfect on native-English essays. The mechanism is brutal in its simplicity: second-language writing tends toward simpler vocabulary and predictable structure, which is exactly what detectors are trained to read as machine-like.
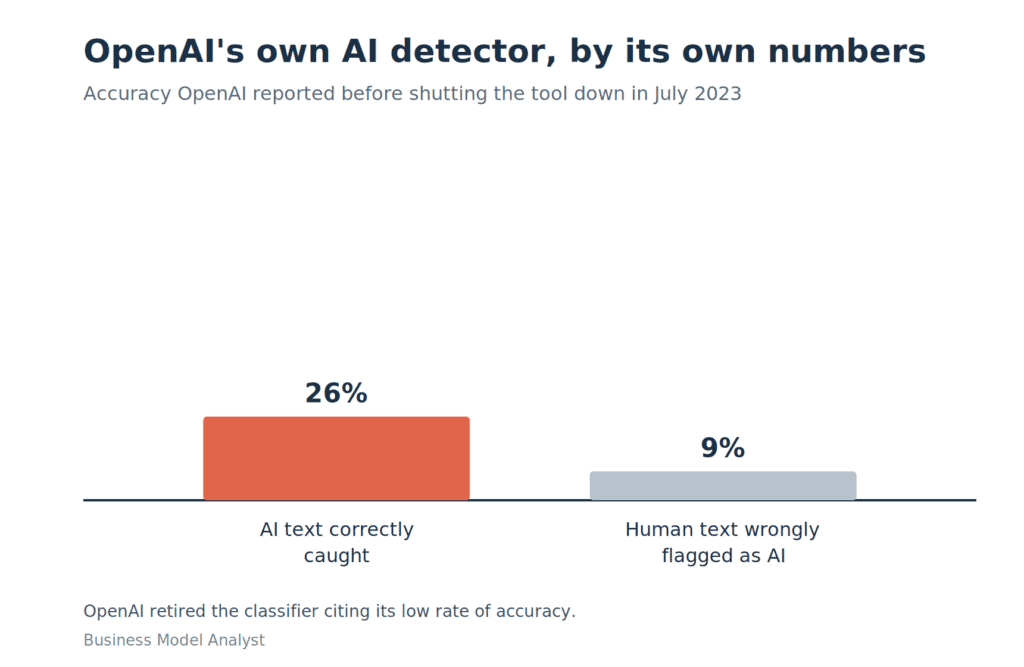
A product that systematically misfires on an identifiable population is not just inaccurate. It is a liability magnet, especially when institutions use it for enforcement. Vanderbilt disabled Turnitin’s AI detector rather than carry that risk. That is a paying customer walking away from a bundled, incumbent feature, which tells you how the enforcement use case actually ages.
The arms race nobody wins
Even set accuracy aside and the business model has a second structural problem: the target moves, and it moves faster than the detector.
Detection and evasion are locked in an arms race where switching costs and moats keep eroding. Every time a detector learns the fingerprint of the current model generation, a new model or a “humanizer” tool launches that erases it. Pangram markets its ability to catch humanizers as a feature, which is honest, but it also reveals the trap. You are selling a subscription against an adversary that updates monthly and pays nothing to counter you. The R&D burden never ends, and any accuracy claim has a short shelf life by construction.
This is why detection looks less like durable infrastructure and more like antivirus in the worst era of antivirus: perpetually one step behind, selling reassurance as much as protection. The company can be busy, even profitable, and still be running to stay in place.
Where the money actually ends up
If detection is structurally leaky, where does the real value in “content provenance” settle? Almost certainly upstream, at the moment of creation, not downstream in a guessing engine.
The durable version of this is cryptographic provenance: content credentials signed at capture or generation, the approach behind industry standards like C2PA that camera makers, Adobe, and the model labs themselves are building toward. If a photo or a document carries a verifiable, tamper-evident record of how it was made, you do not need to guess. You check a signature. That routes the value to the platforms, devices, and model providers that sit at the point of creation, not to a third-party detector inspecting the output after the fact.
Which reframes the $9 million. It is not funding a permanent toll booth on human content. It is funding a bridge across the years before provenance-at-creation becomes standard. That can be a genuinely good venture bet, bridges get acquired, but it is a different and more fragile thing than the “essential infrastructure for the AI age” framing suggests. Even OpenAI’s own roadmap points at provenance techniques rather than detection.
Who actually buys this, and why
The clearest signal in the whole market is the demand side. Look at who pays: universities, recruiters, publishers, arXiv. These are institutions that have to make a judgment they would rather not own. arXiv now warns that submissions showing evidence the authors never reviewed their LLM output, like hallucinated citations or a stray “Would you like me to make any changes?”, can trigger a one-year ban.
Detection is being bought as a way to convert a hard, subjective, reputationally risky decision into an outsourced, seemingly objective score. That is a real and recurring need, which is why the revenue exists. But it also means the product is doing reputational and legal cover work, not truth work. The moment a false positive becomes a lawsuit or a scandal, the “objective score” defense collapses, and the buyer remembers it was a probability all along.
Frequently asked questions
Are AI content detectors accurate? On average, the better ones are good, and vendors cite figures above 99%. But averages hide the failures that matter. Detectors produce false positives, struggle against humanizer tools, and have shown strong bias against non-native English writers. OpenAI shut down its own detector in 2023 over low accuracy. Treat any single score as a signal, not a verdict.
How do AI detection companies make money? Mostly through API and enterprise licensing to schools, publishers, platforms, and recruiters, plus consumer subscriptions in the $20-per-month range. The consumer tier is largely a marketing and distribution channel. The durable revenue comes from institutional contracts and from bundling detection with adjacent tools like plagiarism checking and grading.
Can AI detectors be fooled? Yes. Paraphrasing tools, “humanizers,” and simple prompt engineering can lower detection scores, which is why the category is a constant arms race. Detectors improve, evasion improves, and the cycle repeats. No detector stays ahead permanently.
Will Google penalize my site for using an AI detector’s target content? Third-party detectors like Pangram do not feed Google Search or Discover rankings. Google runs its own systems and has said it rewards helpful content regardless of how it is produced. A browser extension labeling a post as AI has no direct bearing on search visibility.
Is AI detection a good business to be in? It is a fundable business with real, recurring institutional demand. Whether it is durable is the open question. The accuracy ceiling, the false-positive liability, the perpetual arms race, and the rise of provenance-at-creation standards all cut against it becoming permanent infrastructure. It looks more like a strong bridge business than a forever business.
The Business Model Analyst Take
The Pangram raise is a good business decision inside a category with a broken center. The demand is real, because institutions will always pay to outsource an uncomfortable judgment, and the enterprise-plus-bundling revenue model is sound. The problem is the product underneath: a probability sold as proof, misfiring on real humans at scale, chasing an adversary that improves for free, in a world drifting toward cryptographic provenance that will eventually make output-side guessing unnecessary.
The smart money read is that these companies are not building the toll booth on human content they describe. They are building acquisition targets and bridge products for the messy middle years, and the winners will be the ones, like GPTZero, who bolt detection onto a workflow customers already pay for so that the business survives even after the detector itself stops being special. Detection is the hook. The workflow is the business. Anyone evaluating this space, as an operator, an investor, or a buyer, should price the detector at close to zero and value everything attached to it instead.