Zhipu’s open-weight GLM-5.2 matches restricted US frontier models on security tasks at a sixth of the cost, and the controls meant to contain that capability are leaking value to the open layer.
Security researchers found that Zhipu’s freely downloadable GLM-5.2 matches the bug-finding ability of Anthropic’s restricted Mythos model and beat Claude Opus 4.8 on one benchmark, at roughly a sixth of the cost. The exact capability Washington locked down arrived as a free, MIT-licensed download within days.
Here is the part that should make every policy hawk wince. The US government pulled its most capable models off the market for security reasons. A Chinese lab then released a model that does the headline-grabbing piece of that job, finding vulnerabilities in code, for the price of a coffee per thousand scans. You cannot un-download a model. That asymmetry is now the whole story.
What Happened
Cybersecurity firm Semgrep ran a batch of open-weight models against its internal vulnerability-detection benchmark and got a result it openly called surprising. On an IDOR detection test, with no special scaffolding and the same prompt it gives frontier coding agents, GLM-5.2 scored 39% F1 and beat Claude Code at 32%, at about $0.17 per vulnerability found. A separate evaluation by Graphistry found GLM-5.2 matched Opus 4.8 on a capture-the-flag style security benchmark, making it the first open-weight model the firm said it would recommend for frontier-level security work.
The takeaway researchers gave the Wall Street Journal: with a bit more prompting, both Opus 4.8 and GLM-5.2 can match Anthropic’s restricted Mythos on bug-finding. On the same day, China’s 360 Security unveiled a bug-finding tool it called comparable to Mythos, with its CEO arguing this class of capability “can’t remain solely in American hands.”
GLM-5.2 is a roughly 750-billion-parameter mixture-of-experts model with a 1-million-token context window, released under a permissive MIT license. It already ranks among the ten most-used models on OpenRouter.
The Backstory
The timing is not a coincidence. On June 12, a US export directive forced Anthropic to disable broad access to its top models, Mythos 5 and the more guarded Fable 5, to keep foreign nationals out. We covered the strange business fallout when the “too dangerous to use” label started boosting Anthropic’s enterprise sales. Days later, OpenAI limited access to GPT-5.6 on similar grounds. Zhipu shipped GLM-5.2’s open weights into exactly that vacuum.
The capability gap was already closing fast. By May 2026, Chinese open-weight models accounted for roughly 61% of all tokens consumed on OpenRouter, and four of the five most-used models were Chinese, a shift we mapped in the AI margin-migration breakdown. GLM-5.2 did not start that trend. It accelerated it.
The Plan
Zhipu’s move is a business-model decision dressed as a research release. The company gives the weights away under MIT, with no regional locks, then monetizes through its hosted API and a flat-rate GLM Coding Plan that slots into tools like Claude Code, Cursor, and VS Code. Giving the model away is the marketing. The subscription and the cloud API are the register.
The market liked it. Zhipu’s Hong Kong-listed entity surged as much as 48% in a week after the launch, with JPMorgan lifting its price target and Bank of America initiating with a buy. An open release became a stock catalyst, which tells you how the street is now pricing the open layer.
The Business Model Angle
Strip away the cyberwarfare framing and this is a pricing story. GLM-5.2 lists around $1.40 per million input tokens and $4.40 per million output tokens. Claude Opus 4.8 runs $5 and $25. GPT-5.5 runs $5 and $30. On the output tokens that dominate agentic coding bills, the open Chinese model is roughly six times cheaper.
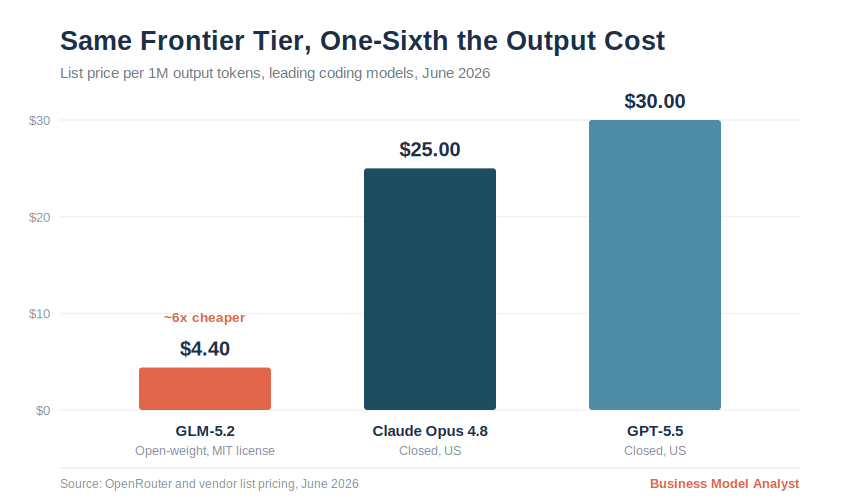
That gap is the engine. Export controls can only touch the thing the US controls, which is closed-weight access. They do nothing to a model already sitting on a hard drive in 40 countries. So the policy does two things at once: it removes the cheapest, most capable American option from the shelf, and it makes the cheap Chinese substitute the obvious default for any cost-sensitive buyer. The capability you wanted to contain is the capability you just advertised.
The benchmark picture, for the record, is more mixed than the headline:
| Benchmark | GLM-5.2 | Claude Opus 4.8 | What it measures |
|---|---|---|---|
| Semgrep IDOR (F1) | 39% | 32% (Claude Code) | Raw vulnerability detection |
| SWE-bench Pro | 62.1 | 69.2 | Real-world coding fixes |
| SWE-Marathon | 13.0 | 26.0 | Long-horizon hard reasoning |
GLM-5.2 wins the narrow security task and loses the hard reasoning one. That nuance is exactly what the “China matched the US” framing flattens.
The Risk
Three things should temper the panic, and one should deepen it.
First, Semgrep was blunt that this was one dataset, one run, one task, and that its own purpose-built harness (53% to 61% F1) still crushed every raw model. The harness matters more than the model, which means the parity claim is narrower than the headline. Vercel’s Guillermo Rauch made the same point: the circulating numbers come from a single Semgrep test, not a head-to-head against Mythos itself.
Second, anyone routing through Zhipu’s cloud API is subject to Chinese law. That risk evaporates with self-hosting the open weights, but most buyers will not self-host.
Third, the unsettling part. Graphistry flagged a statistical anomaly suggesting GLM-5.2’s outputs correlate unusually closely with Opus 4.8 and GPT-5.5, raising distillation questions about whether the model learned partly by interrogating the very US systems now restricted. If true, the open Chinese frontier is being built, in part, on the closed American one. Restricting access does not fix that. The training already happened.
Quick Questions
Is GLM-5.2 actually better than US models?
No. It beats Claude Code on one narrow security benchmark and matches Opus 4.8 on another, but trails on harder reasoning tasks. The story is “good enough and far cheaper,” not “best.”
Why does open-weight matter here?
Because open weights can be downloaded, modified, and run by anyone, including hackers who can strip safety controls. Closed models from Anthropic and OpenAI can be restricted at the API. A downloaded model cannot be recalled.
How much cheaper is it?
Roughly six times cheaper on output tokens, the cost that dominates agentic coding workloads.
How does Zhipu make money giving the model away?
Through its hosted API and a flat-rate GLM Coding Plan subscription. The free weights drive adoption; the cloud and subscription tiers capture revenue. It is the same playbook that powers the DeepSeek business model.
Did US policy cause this?
Not the model itself, but the timing and the demand. Restricting top US models created the exact opening a free, capable substitute walked into.
The Business Model Analyst Take
The cyberwarfare headline is the part that travels, but the durable lesson is about market structure. Export controls assume the thing of value is access. In an open-weight world, the thing of value is the weights, and weights do not respect borders once they ship. Washington restricted the one layer it could touch, the closed American frontier, and in doing so handed the price-sensitive majority a reason to standardize on the open Chinese layer it cannot touch at all.
For operators, the practical read is simpler than the geopolitics. The open model tier is now good enough for a widening band of real work at a fraction of the cost, and the quarterly cadence out of China keeps compressing the gap. If your stack still assumes the frontier is exclusively American and exclusively closed, that assumption is aging in dog years. The interesting question is no longer whether the cheap open model is competitive. It is which parts of your workload still justify paying six times more, and whether that list is shrinking faster than your budget can absorb.
Reporting drawn from the Wall Street Journal, Semgrep’s published benchmarks, and OpenRouter pricing and usage data, June 2026.