
What is AI text watermarking? It is a way of marking machine-written text by controlling the randomness a model uses to pick between words that would work equally well. The pattern is invisible to a reader and detectable by anyone holding the key. Its coverage is not uniform. It is dense in free-flowing prose, thin in factual writing, and close to absent in code, because the mark can only live in choices the model was genuinely free to make.
Every provenance business being funded right now rests on an assumption nobody has priced: that a watermark covers the content people care about verifying. It does not. It covers the opposite.
The mark is thickest in a blog post and thinnest in a financial statement. It is thick in a marketing email and thin in a legal citation. In code, the place where AI authorship carries the sharpest security and liability consequences, published detection rates on standard watermarking fall as low as 11.5%. Same watermark, same detector, same model. The only thing that changed was the kind of writing.
That is not a bug someone will patch. It is the mechanism working correctly.
How a watermark actually gets made
A language model writes one token at a time. At each step it holds a ranked list of candidates. Most of the time one candidate is obviously right and the rest are wrong. Occasionally two or three are equally fine, and which one lands is settled by a random number.
Watermarking hijacks that coin flip. Instead of drawing from an arbitrary random source, the model derives the number from a secret key plus the words immediately preceding. The output still looks random. But anyone with the key can replay the sequence and ask whether these were the choices the key would have produced. Enough matches, and you can assign a probability that the model wrote it.
Anthropic described the mechanism publicly on 14 August 2026, when it confirmed that Claude uses a version of SynthID-Text, the scheme Google DeepMind published in Nature in 2024. Anthropic also stated the constraint that follows from it: where the output has to be exact, the nudge is not applied. Its own example is arithmetic. Once the model has written “2 + 2 =”, there is no second answer that serves as well as 4, so there is nothing for the watermark to ride on.
Researchers have a word for the thing being consumed here. Entropy. High-entropy tokens are the ones where the model’s probability mass is spread across several plausible options. Low-entropy tokens are near-deterministic. The watermark is a tax on optionality, and it can only collect where optionality exists.
The coverage map nobody publishes
Run that mechanism across the kinds of writing businesses actually produce and a pattern falls out immediately.
| Content type | Free choices available | Expected watermark density | Basis |
|---|---|---|---|
| Translation | Very high, every word is the model’s | Full | Anthropic states translations carry a watermark because the model chooses every word |
| Long-form prose, essays, marketing copy | High | Dense | Highest-entropy text; the regime it was designed against |
| Summaries and general explanation | Moderate to high | Dense | Mostly free phrasing around fixed facts |
| Factual and numeric passages | Low | Sparse | Anthropic states the watermark is sparser where accuracy constrains word choice |
| Code | Very low | Minimal, mostly comments | Anthropic states code carries generally less watermarking; comments are the exception |
| Light proofreading of human text | Near zero | Often none | Anthropic states there may be too few changes to register |
Read the right-hand column and notice something. Every entry is Anthropic describing its own product’s limits. None of this is hostile analysis. The company published the coverage gap itself, in the same document that announced compliance.
The evidence: same watermark, two very different outcomes
The cleanest measurement of the gap comes from a 2024 ACL paper by Lu, Liu, Yu, Li and King, which ran an identical watermark generator and detector across high-entropy and low-entropy tasks and reported detection at a fixed false-positive rate.
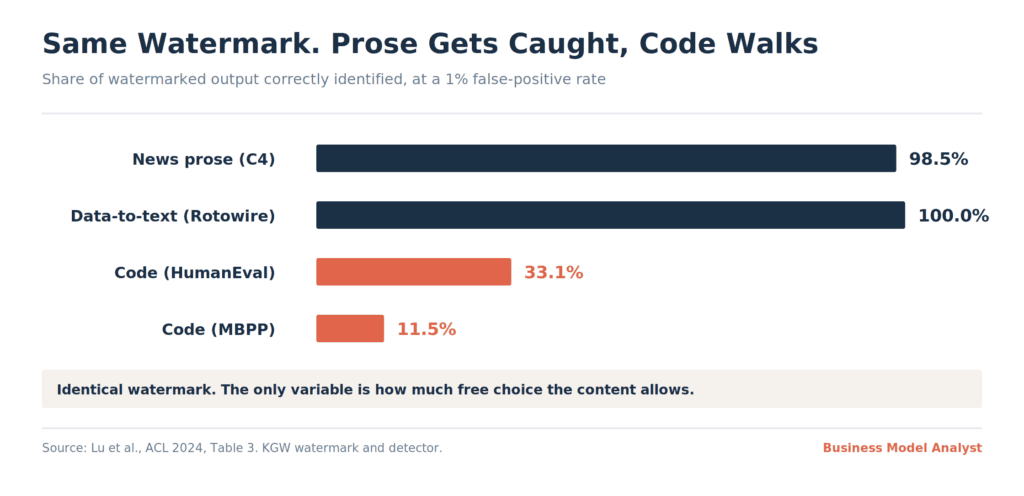
On news prose, the watermark caught 98.5% of generated text. On a data-to-text task, 100%. On the two code benchmarks, 33.1% and 11.5%.
Nothing about the watermark changed between those rows. Nothing about the detector changed. What changed is that Python has grammar, and grammar removes choices. When the next token has to be a colon, a closing bracket or the variable you declared four lines up, the model is not choosing, so the key has nothing to sign.
Purpose-built fixes narrow the gap and do not close it
The obvious response is to build a watermark that handles low-entropy text. Several teams have. They help, and they help less than you would want.
The same paper models the miss rate, the share of watermarked machine output that reads as human-written, for three methods on low-entropy generation, holding all three to an identical 2.28% false-positive rate.
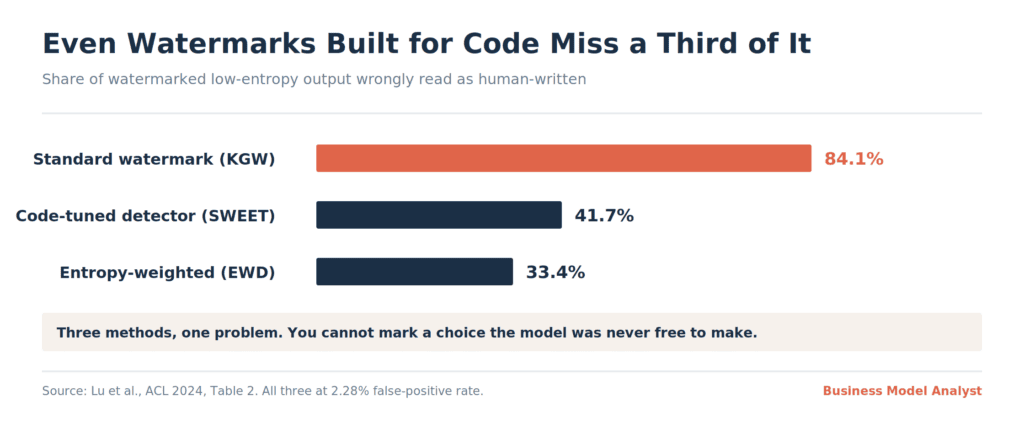
The standard scheme misses 84.1%. SWEET, built specifically for code, cuts that to 41.7%. EWD, which weights each token by its entropy at detection time, gets to 33.4% and remains the best of the three. A third of watermarked code still reads clean.
The purpose-built approach also charges for the improvement in the one currency engineering teams will not pay. The SWEET authors report an AUROC of 0.873 on MBPP and 0.815 on DS-1000, at the cost of roughly a 10% degradation in whether the generated code actually runs. Their strongest result, 0.943 on HumanEval, still costs 2.4% of working code.
| Approach | Detection quality on code | Cost |
|---|---|---|
| Standard watermark | Below 0.8 AUROC on MBPP and DS-1000 | Minimal |
| Distortion-free watermark | Below 0.6 AUROC in every case tested | Minimal |
| Post-hoc AI detectors | Below 0.6 AUROC in every case tested | None, they do not touch generation |
| SWEET, tuned for code | 0.815 to 0.943 AUROC | 2.4% to roughly 10% of working code |
That last column is the whole argument. To make AI-written code reliably detectable, you break some of it. No vendor selling a coding assistant will accept that trade, and no customer would tolerate it if they did. The market has already voted, which is why nothing shipping today makes it.
And then there is the rewrite problem
Coverage is one failure axis. Durability is the other, and it hits the method Anthropic actually uses.
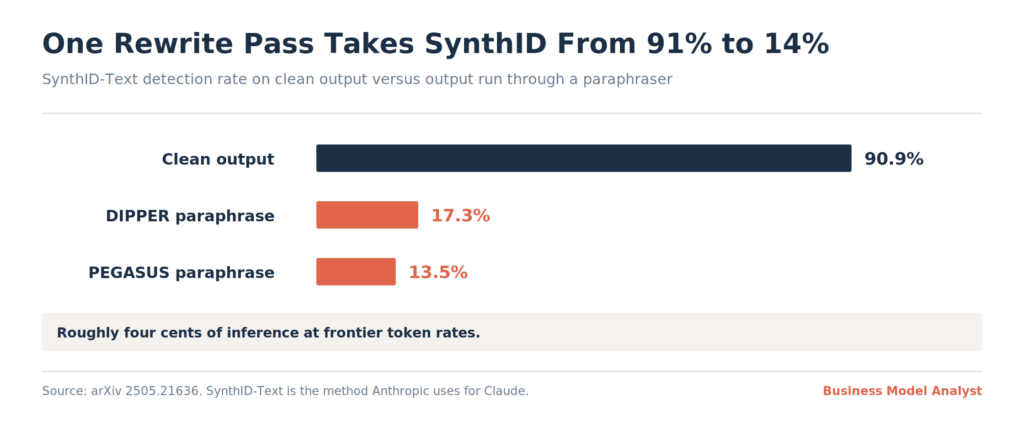
SynthID-Text detects 90.9% of clean output. Run the same text through a paraphrasing model and detection lands at 17.3% or 13.5% depending on the paraphraser. A separate July 2026 forensic evaluation found that meaning-preserving paraphrase eliminated detection in 98.3% of previously detected SynthID texts, measured a 5.4% false-positive rate on clean human writing, and concluded the method fails at least two of the five Daubert factors US courts apply to expert evidence.
Anthropic’s own position is more forgiving. It says light editing probably will not remove the mark completely, and that a full rewrite replacing every word will, at which point it questions whether the text is still AI-generated in any meaningful sense. That is a reasonable philosophical position and a weak operational one. The published research on the same method puts the threshold at one automated pass, and at frontier token rates that pass costs about four cents on a 1,000-word article, as our breakdown of AI token economics lays out. The paraphraser also has to be an unmarked model, which describes most of the cheap ones.
The business model angle: coverage runs inverse to willingness to pay
Now put the two maps on top of each other. Where is the watermark dense, and where would somebody actually pay to know?
| Who wants provenance | What they need verified | Watermark coverage | What they will pay |
|---|---|---|---|
| Banks, auditors, regulated filers | Numbers, disclosures, factual claims | Sparse | High |
| Law firms and courts | Citations, case references, filings | Sparse | High |
| Security and software procurement | Code and dependencies | Minimal | High |
| Universities and schools | Essays and written assignments | Dense | Moderate, budget-constrained |
| Publishers and platforms | Articles, posts, newsletters | Dense | Moderate, ad-funded |
| Agencies and content buyers | Marketing copy and blog posts | Dense | Low |
The correlation runs the wrong way, and it runs the wrong way for a structural reason rather than a coincidental one. The buyers with money are the ones facing consequences for being wrong about a fact, a number, a citation or a line of code. Precision is what makes their content valuable and precision is what starves the watermark. The buyers the watermark serves well are the ones whose content is valuable because it is fluent, and fluency is cheap to fake and cheaper to care about.
Three commercial consequences follow.
Provenance-at-output is a features business, not an infrastructure business. A signal that works on blog posts and fails on filings cannot be the trust layer of anything. It can be a checkbox in a procurement questionnaire, which is a real if modest product. Anthropic’s own detection API, still undated, will inherit these limits on day one. Nobody should build a company on reselling access to it.
The money moves to attestation, not inspection. If you cannot reliably read authorship out of the artifact, you record it at the point of creation instead. That is the C2PA logic Anthropic already applies to image files, and it is why the durable version of this market looks like signed workflow logs, tool-use records and audit trails rather than a scanner pointed at finished text. We made a version of this argument in how AI detectors make money: the value routes to whoever sits at the point of creation, not to whoever inspects the output afterwards. The entropy gap is the technical reason that has to be true.
Behavioural detection keeps its market longer than expected. Stylometric detectors like Pangram and GPTZero do not need a key and do not care about entropy. They read habits. Anthropic itself pointed at two in its explainer, noting that models overuse a particular contrastive construction and reach for the word “quietly” far more than people do. Those tells are soft, they produce false positives, and they will be trained away eventually. But on a factual report or a code file, a soft signal that exists beats a hard signal that does not.
Where this leaves the people writing the checks
For a services business, the practical read is narrower than the regulatory noise suggests. Your exposure tracks how much of the deliverable the model actually wrote. Translation carries a full mark. Ghostwritten prose carries a heavy one. A financial model with commentary carries less than you would guess. A code repository carries almost nothing. Price and disclose accordingly, and do it before a client contract does it for you.
For anyone building in the space, the addressable market is not “content.” It is the subset of content that is both high-entropy and worth verifying, and that subset is smaller and poorer than the funding rounds imply.
For the buyers of AI coding tools, there is a quieter point. The most consequential category of AI-generated artifact in the economy is currently the least markable one, and the vendors shipping it have no commercial reason to change that. Whatever governance framework a company writes for AI-generated code, it will not be enforced by inspecting the code. It will be enforced by logging who ran what, which is a process problem wearing a technology costume. The economics of that market, and the pressure on the companies selling into it, point the same way.
The counterargument worth taking seriously
The strongest case against all of this is that coverage is the wrong metric.
Watermarking was never designed to catch a determined adversary. It was designed to make casual undisclosed use visible at scale, and casual undisclosed use is overwhelmingly high-entropy prose: the essay, the blog post, the review, the newsletter. On that population the mark works well, and a 98.5% detection rate on prose is not a failure by any standard. Regulators asking for machine-readable marking of synthetic content got a tool that does the job on the content they were worried about, which was disinformation and impersonation, not audited financial statements.
There is a second point in the same direction. The mark is one input, not a verdict. In a procurement or compliance setting it sits alongside vendor attestations, contractual warranties and tool-use logs, and a partial signal genuinely does raise the cost of lying even when it cannot prove anything on its own.
Both points land. Neither one rescues the investment thesis, because a tool that works on the cheap end of the content market and fails on the expensive end is a tool with a ceiling on what anyone will pay for it. The question was never whether watermarking does something useful. It is whether it does something monetisable at the scale being funded.
Frequently asked questions
Does AI watermarking work on code? Barely. Anthropic states that code carries generally less watermarking than other text because so much of it must be exact. Published benchmarks put standard watermark detection on code as low as 11.5% at a 1% false-positive rate. Comments inside code can be marked. The executable code mostly cannot.
Why is the watermark weaker on factual writing? Because a watermark can only occupy choices the model was free to make. When only one word is correct, the model has no freedom to encode anything into. Anthropic gives this as the reason its own mark is sparser on factual passages.
Can a watermark be removed? Anthropic says light editing probably will not remove it completely and a full rewrite will. Published research on SynthID, the method Anthropic uses, is less generous, showing detection falling to between 13.5% and 17.3% after a single automated paraphrase pass.
Does the absence of a watermark prove a human wrote something? No. Anthropic says this directly. Short passages, older models, code, factual text, edited text and text from a different provider can all come back clean.
What replaces watermarking? Provenance recorded at the moment of creation rather than read out of the finished artifact. C2PA content credentials for files are the existing standard. For text and code, the practical equivalent is signed tool-use logs and workflow attestation, which is a documentation problem more than a cryptography one.
Is AI detection software affected by the same limits? Differently. Stylometric detectors read writing habits rather than a key, so entropy does not constrain them the same way. They carry their own weakness, a false-positive rate that punishes people who did nothing wrong.
The Business Model Analyst Take
The uncomfortable thing about this watermark is that it is honest. Anthropic published its own coverage gap, in detail, in the same document that announced compliance. It did not have to. Almost nobody reading the announcement will get as far as the sentence about code.
But an honest instrument with a structural blind spot is still an instrument with a structural blind spot, and this one is aimed away from the money. It reads the content of a marketing agency and goes quiet on the content of an investment bank. It reads a student essay and goes quiet on a pull request. Whatever gets built on top of it inherits that shape, and the shape does not improve with better engineering, because the constraint is not engineering. You cannot record a decision that was never made.
The practical conclusion is the one that keeps surfacing in this cycle, as we argued in AI is winning where the answer can be checked. Verification is the scarce asset, and it stays scarce precisely where it would be worth the most. Watermarking is the content industry’s version of that lesson: a real capability, correctly built, that happens to be strongest in the market segment least able to pay for it and weakest in the one that would write the cheque. The winners in provenance will not be the companies reading marks out of finished text. They will be the ones recording what happened while it was being written, and selling the receipt.