
Ten years after Move 37, the pattern in every AI breakthrough is the same: a cheap, automatic scoreboard. Most of the economy does not have one.
Artificial intelligence has torn through mathematics and code in roughly three years because both domains can grade their own homework at almost zero cost. Drug discovery, chemistry and biology cannot, which is why the most decorated man in AI is now telling reporters those fields will need human judgment for a long time. That gap is not a research detail. It is the load-bearing assumption underneath about $700 billion of 2026 capital spending, and it decides which industries get their margins vaporized and which ones keep charging for expertise.
A decade ago a computer put a stone on a Go board in a spot no professional would have chosen, and the world decided AI was real. Ten years later, the more useful question is not what the machine knew. It is what let the machine find out that it was right.
What Happened
The Wall Street Journal’s Ben Cohen published a column on August 7 marking ten years since AlphaGo’s Move 37, the play against Lee Sedol that DeepMind’s own team put at one-in-ten-thousand odds of coming from a human. Cohen spoke with Demis Hassabis, who has just moved from DeepMind CEO to Google chief scientist and DeepMind chair, about how many Move 37 moments are now arriving at once.
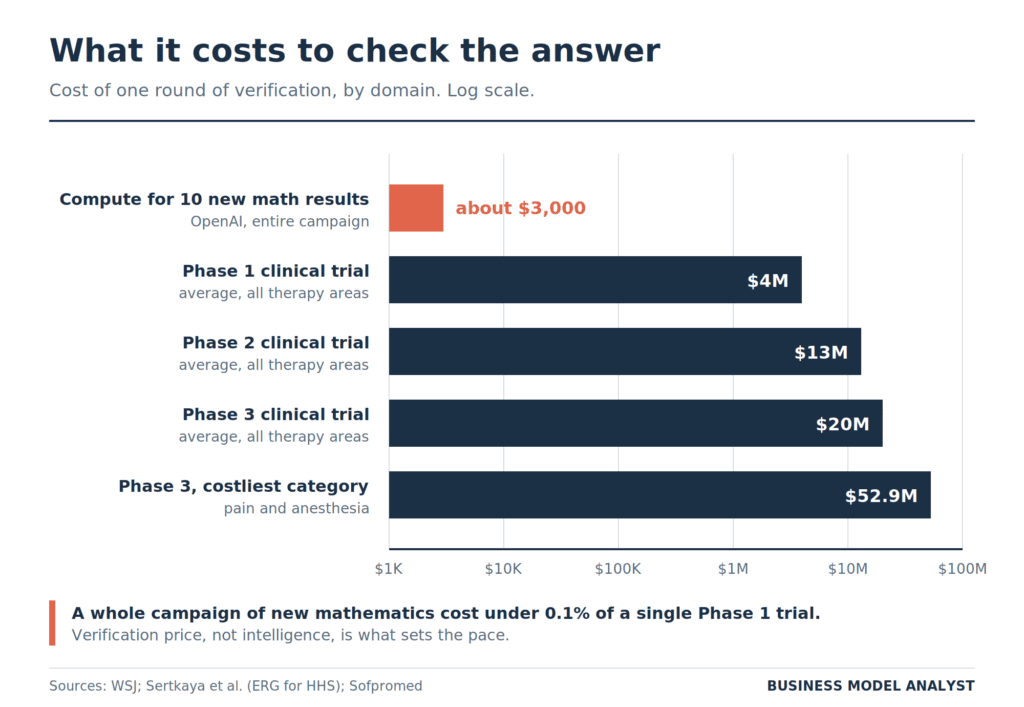
The math ledger Cohen assembles is the striking part. In 2023 AI models were still fumbling elementary arithmetic. In 2024 a DeepMind silver medal at the International Mathematical Olympiad counted as a landmark. By 2025 both DeepMind and OpenAI were taking gold. By 2026 the achievement had become so routine that Anthropic reported a perfect Olympiad score on page 153 of a technical document. Beyond school competitions, OpenAI’s model cracked a major Erdős problem, Anthropic’s disproved a well-known conjecture, and OpenAI spent a few thousand dollars of compute to generate ten separate advances across high-dimensional geometry, lattice cryptography, arithmetic circuit complexity and other fields.
Then Cohen supplies the explanation, almost in passing. Math fell fast because math is unusually verifiable. Proofs can be checked line by line against fixed logical rules, so a model can try, test, learn and retry until something holds. Hassabis draws the boundary himself when the conversation turns to the messy sciences: drug discovery, biology and chemistry are emergent and, in his words, “you can’t verify everything.”
The Backstory
Move 37 was never really a story about raw intelligence. It was a story about a scoreboard.
Go has a win condition. That means a system can play itself millions of times and receive an unambiguous verdict every single game, for free, forever. Reinforcement learning is not magic applied to a board game. It is a search process that needs a cheap, fast, trustworthy referee. Where the referee is cheap, the search runs hot and the machine finds things no human would try. Where the referee is expensive, the search barely runs at all.
AI researcher Andrej Karpathy’s definition of the phenomenon, which Cohen quotes, describes moves that are new, surprising and quietly brilliant even to experts. Note the precondition buried in it: the system has to be trained through trial and error, which requires trials that can be scored.
Chess supplies the sequel nobody likes to mention. After Deep Blue beat Kasparov in 1997, a format emerged where humans consulted engines, and for a while these centaurs beat engines running alone. That window closed. Human input eventually stopped adding signal and started adding noise. Hassabis now says science is entering its own centaur era and that in genuinely complex domains it could last a very long time. He is describing a business model with an expiry date that nobody can read.
The Plan
Look at what the industry is actually building, and it is sequencing itself by verification cost rather than by market size.
Discovery Loop, the startup Jeff Dean and three other senior Google researchers left to found last week, published a roadmap that reads like a verifiability ladder: automate machine learning research and engineering first, then hardware design, then drug discovery, then clean energy. Those are not ordered by value. Drug discovery and clean energy are worth vastly more than ML engineering. They are ordered by how cheaply you can find out whether the machine was right. We covered the deal structure behind that departure in our piece on how Jeff Dean’s exit cost Alphabet $190 billion, and the roadmap is the part the market underpriced.
Enterprise spending shows the same shape. Coding, the most verifiable commercial task in existence, absorbs the majority of departmental AI budgets. Every unit test, type checker and CI pipeline built over the last twenty years turns out to have been infrastructure for reinforcement learning, built by people who had no idea that was what they were doing.
Meanwhile the capital keeps arriving. The four largest hyperscalers have guided toward roughly $700 billion of 2026 capital expenditure, with Alphabet alone raising its range to $195 to $205 billion after its second quarter print and going free-cash-flow negative in the process. That spending is not underwritten by better performance on proofs. It is underwritten by the belief that the same loop keeps working once you leave the domains where checking is free.
The Business Model Angle
Verifiability is the variable that decides where AI collapses a cost curve, and it produces three consequences that most operators are not pricing.
First, verifiable domains commoditize the fastest, which is bad news for anyone selling into them. When checking is free, every model gets good at the task, and good stops being scarce. Mathematics is the pure case: AI conquered it and there is no revenue line at the end of it. Code is the commercial case, and the price war there is already visible in per-token pricing and routing behavior. The margin does not stay with whoever produces the output. It migrates toward whoever owns the constrained input, which is the argument we laid out in the AI bubble debate is asking the wrong question.
Second, unverifiable domains protect human pricing power, but they cap growth at the verification budget rather than at the intelligence budget. Isomorphic Labs, Hassabis’s own drug company, is the natural experiment. Founded in 2021, built on a Nobel-winning structure prediction breakthrough, funded with $600 million led by Thrive Capital, and its first-in-human trial has slipped from end of 2025 to end of 2026. Not because the models got worse. Because a Phase 1 trial costs around $4 million on average and takes real time with real patients, and no amount of compute compresses that.
Put the two together and the arithmetic is brutal. OpenAI generated ten new mathematical results for the price of a modest software contract. One Phase 1 trial costs more than a thousand times that. In pain and anesthesia, one Phase 3 runs to $52.9 million. The RL flywheel does not slow down in biology because biology is harder to think about. It slows down because each turn of the crank has a seven-figure invoice attached.
Third, and this is the part almost nobody is selling: the scarce asset in the next cycle is ground truth, not model quality. If verification cost is the rate limiter, then anyone who manufactures a cheap, trustworthy scoreboard for a messy domain converts that domain from centaur mode to flywheel mode. Simulation environments, formal specification layers, automated wet labs, evaluation harnesses and domain-specific benchmarks are usually filed under research overhead. They are actually the picks and shovels of the next phase, and they are priced like a cost center.
The uncomfortable corollary for the capex program is straightforward. Every one of the breakthroughs being cited as evidence that the spending is justified comes from the narrow band of the economy where the scoreboard is free. The explanation for those breakthroughs is that the band is narrow. Both things cannot be evidence for the same thesis.
The Risk
The obvious risk is timing. Depreciation schedules on AI hardware run roughly six years. Hassabis is describing a centaur period in the highest-value domains that could last considerably longer than that. If the messy sciences take fifteen years to yield, the assets bought to attack them will have been written off twice before the revenue shows up.
The subtler risk is homogenization. Cohen notes the strange aftermath of AlphaGo: professional players got measurably better and also became far more alike, and Lee Sedol retired saying the game had stopped being enjoyable. Transfer that to business and the picture is unattractive. In verifiable domains, everyone’s output quality rises and variance collapses. Rising quality with falling variance is the definition of a commodity. AI works best precisely where differentiation dies fastest.
Then there is the risk companies are creating for themselves. In unverifiable domains the only available referee is human review, and firms are busy deleting it. Our earlier reporting on what happens when AI agents get added to the org chart found managers caught noticeably fewer errors once they believed an AI colleague produced the work. That is the verification layer thinning out in exactly the settings where it is the only thing standing between a plausible answer and a wrong one.
The honest counterargument deserves space, because it is strong. Verifiability is not a fixed property of a domain. It is an engineering variable. Coding was not obviously verifiable until an industry spent two decades building test harnesses. Protein structure prediction became verifiable because CASP built a benchmark for it. Simulation, automated laboratories and synthetic environments can all lower the price of checking, and that is precisely what a large slice of AI research spending is aimed at. The boundary moves. Anyone treating today’s line as permanent will be wrong.
Two other pushbacks land. Commodity is not the same as worthless, as cloud computing demonstrated at enormous scale. And revenue in the verifiable band is real revenue today, funding everything else, which is more than most speculative technology cycles could say. The bear case here is about the pace and the shape of returns, not about whether returns exist.
Quick Questions
Why did AI conquer math before it conquered medicine? Because math grades itself. Proofs are checked against fixed logical rules at near zero cost, which lets a model run millions of trial-and-error cycles. Medicine requires clinical trials that cost millions of dollars and take years per cycle.
Does this mean AI cannot do drug discovery? No. It means the loop turns far more slowly and stays expensive. AI is already reshaping the design stage. The bottleneck sits at the point where a hypothesis has to be tested in biology, and that step has not gotten meaningfully cheaper.
Which industries are most exposed? The ones where output correctness is cheap to check: software, quantitative finance, structured legal review, technical documentation, parts of accounting. Exposure cuts both ways, delivering the biggest productivity gains and the fastest price compression.
Which businesses does this favor? Anyone who can lower the cost of verification in a messy domain. Simulation platforms, automated laboratories, evaluation and benchmark infrastructure, and formal specification tooling. Also, for now, human experts whose judgment cannot be scored automatically.
What should an operator actually do with this? Sort your workflows by how much it costs to know the output was correct. The cheap-to-check ones will be automated and will stop being differentiators. The expensive-to-check ones are where your pricing power lives, and where your review process is worth protecting rather than cutting.
The Business Model Analyst Take
The Move 37 framing flatters the machine, and that is why it keeps getting repeated. The more useful framing flatters the referee. Every headline breakthrough of the last three years has happened inside a domain that could tell the system, instantly and for free, whether it had just done something clever or something stupid. Remove that and the same models produce fluent, confident, unfalsifiable output, which is a different product with a very different business model attached.
Which means the AI industry has a product category sitting in plain sight that nobody is packaging. Everyone is selling intelligence. Almost nobody is selling verification. The labs treat evaluation infrastructure as internal cost, enterprises treat human review as overhead to be cut, and investors underwrite capex on capability curves drawn from the one part of the economy where checking is already solved. The gap between what AI can do and what AI can be trusted to have done is not a research problem waiting on a bigger model. It is a market, and it is unclaimed.
Cohen closes his column by saying the rest of us will have to find our Move 78, the beautiful counterplay Lee Sedol found in game four. Fair enough. But Lee’s move worked because the board told everyone immediately that it had worked. The businesses that win the next decade will not be the ones that out-think the machine. They will be the ones that own the board.