
American AI companies have a new grievance, and they are taking it to Congress. Their complaint is not about chips, funding, or talent. It is about a copying technique called distillation, and they say Chinese rivals are using it at industrial scale to shrink the lead that US labs spent billions of dollars building.
On June 10, 2026, Anthropic sent a letter to Senators Tim Scott and Elizabeth Warren, the chair and ranking member of the Senate Banking Committee, accusing Alibaba of what it called the largest known distillation attack against its Claude models. The letter, confirmed by CNBC, claims operators tied to Alibaba’s Qwen AI lab ran roughly 28.8 million exchanges with Claude using about 25,000 fraudulent accounts between late April and early June, then used the harvested outputs to train their own systems.
For a business built on the value of a proprietary model, that is the whole ballgame. So the interesting question is not whether US labs are annoyed. It is whether the thing they are angry about is actually the reason China is catching up, and whether anything Washington does can stop it.
What distillation actually is
Distillation is old, boring, and completely legitimate in its original form. A small team at Google developed it in the early 2010s as a way to make AI cheaper to run. The idea is simple: you take a large, expensive model (the teacher) and use its outputs to train a smaller, cheaper model (the student) to imitate its behavior. The student ends up punching above its weight, and it runs on hardware that costs a fraction as much.
Labs distill their own models all the time. They also distill open-source models, which is exactly what open-source is designed to invite. The friction starts when a company distills a competitor’s proprietary model, the paid, closed system that represents the rival’s core product. Anthropic and OpenAI both ban this in their terms of service. It happens anyway, and not only in China. Testifying in a federal trial in Oakland this April, Elon Musk conceded the practice at his own lab, telling the court that “Generally A.I. companies distill other A.I. companies.”
That admission matters, because it undercuts the cleanest version of the US argument. Distillation is not a uniquely Chinese trick. It is a standard industry shortcut. What US labs are really objecting to is scale, intent, and who benefits.
Why the timing is not a coincidence
Anthropic’s Alibaba letter did not come out of nowhere. In February, the company flagged three earlier campaigns it traced to Chinese labs DeepSeek, Moonshot, and MiniMax, describing roughly 24,000 accounts and 16 million harvested conversations. OpenAI separately accused DeepSeek of the same thing. So the volume of reported distillation against a single US lab has escalated sharply in a matter of months, from 16 million exchanges across three actors to nearly 29 million from one.
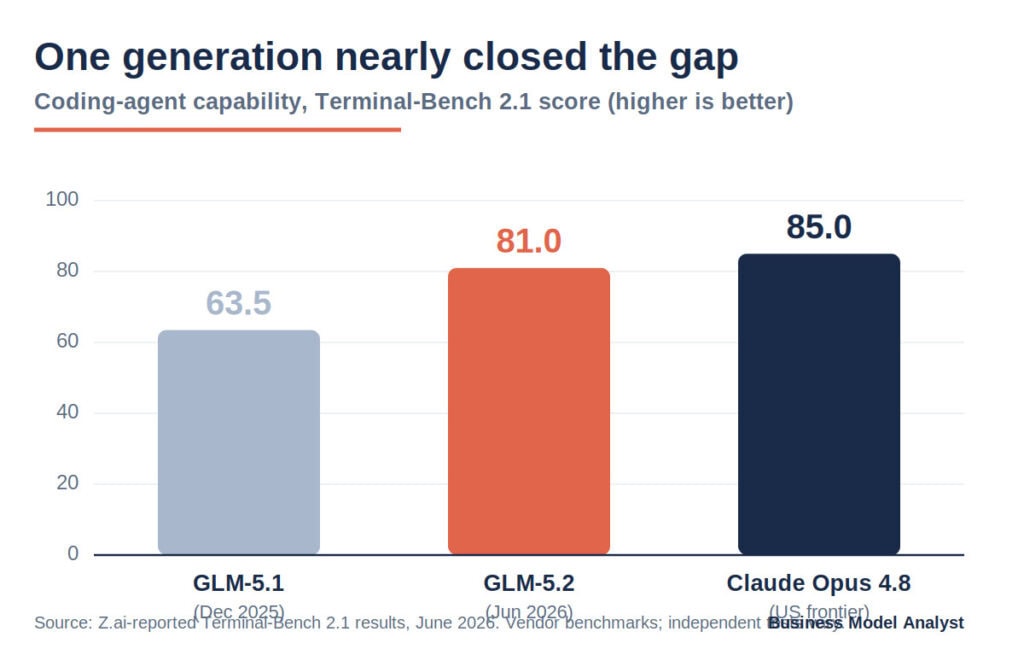
But the real trigger is a product, not a letter. In mid-June, the Chinese startup Z.ai (formerly Zhipu AI) released GLM-5.2, an open-weight model that landed like a thunderclap. On coding and agentic benchmarks it sits within a few points of the top American systems, and independent security firms found it matching or beating US models on the specific task of finding software vulnerabilities. Semgrep measured it outscoring Claude Code on an access-control bug benchmark at roughly seventeen cents per bug found. Axios reported that hackers were already trading jailbreaks for it on Russian-language forums within days.
The chart below shows the part that rattled US labs. In a single generation, GLM went from clearly behind to nearly level.
Researchers at Graphistry went further, suggesting GLM-5.2 may itself be a distillation of leading US models, a claim Z.ai has not addressed. If true, it is a tidy illustration of the whole complaint. If false, it is an even bigger problem for the US argument, because it would mean a Chinese lab reached the frontier without needing to copy anyone.
The business stakes are larger than the benchmark
Here is why this is a business story and not just a research spat. The entire commercial logic of a frontier lab rests on a moat: spend enormous sums training a model that competitors cannot easily replicate, then rent access to it through an API. Distillation attacks the moat directly. If a rival can approximate your most valuable capabilities for the cost of some API calls and a swarm of fake accounts, your pricing power erodes and your years-long lead compresses into months.
The knock-on effects are already visible. Alibaba shares slid to a multi-month low after the accusations surfaced. Bipartisan senators are reportedly working to attach an amendment to must-pass defense legislation that would sanction Chinese firms found to be improperly accessing US models. And the fight is tangled up with export policy: two days after Anthropic’s letter, the Commerce Department restricted access to Anthropic’s most advanced Mythos and Fable models over national security concerns, briefly forcing them offline. Anthropic wants Washington to extend chip export controls further, on the logic that distillation is hard to do without high-end hardware.
The problem with that logic is GLM-5.2 itself. It ships under a permissive MIT license, which means anyone can download the weights and run them locally, with no provider sitting in the middle to shut down suspicious accounts or enforce terms of service. Once open weights are mirrored widely, there is no choke point left for an export order to grab. The control regime the US built assumes a vendor stands between the model and the user. Open weights remove the vendor.
The case that a crackdown will not work
Plenty of experts think US labs are fighting the last war. Two arguments stand out.
First, distillation alone cannot build a frontier model. You can copy a teacher’s outputs, but you cannot copy the research, data pipeline, and infrastructure that produced the teacher in the first place. A model as capable as GLM-5.2 required real capability underneath, not just harvested transcripts. On this view, distillation accelerates a fast follower but does not create one.
Second, the technique may simply matter less going forward. The next era of AI is about agents, digital workers that chain together tools and carry out long multi-step tasks. Training an agent is far harder to replicate by imitation than training a chatbot, because so much of the skill lives in messy, interactive trajectories rather than clean question-and-answer pairs. As Sara Hooker, chief executive of the research lab Adaption, put it, distillation “won’t matter as much for the next era of A.I.”
There is also the enforcement reality. Legal scholars are split on whether distillation even violates the 2016 Defend Trade Secrets Act, and courts have not ruled. Copyright is a weak fit, because distillation copies behavior rather than text. And most of the conduct happens outside US jurisdiction, which makes a US court order close to unenforceable regardless of what it says.
Frequently asked questions
What is AI distillation?
Distillation is a training method where a smaller model (the student) learns to imitate the outputs of a larger, more capable model (the teacher). Google researchers developed it in the early 2010s to make AI cheaper to run. It is legitimate and common when a lab distills its own models or open-source ones. It becomes contentious when a company distills a competitor’s paid, proprietary model.
Is AI distillation illegal?
It is not clearly illegal. Legal scholars are divided on whether distilling a rival’s model violates the 2016 Defend Trade Secrets Act, and no court has ruled on it. Copyright is a weak fit because distillation copies a model’s behavior rather than its text. Enforcement is also difficult when the activity happens outside US jurisdiction.
What did Anthropic accuse Alibaba of?
In a June 10, 2026 letter to Senators Tim Scott and Elizabeth Warren, Anthropic accused Alibaba’s Qwen AI lab of the largest known distillation attack against its Claude models. It alleged roughly 25,000 fraudulent accounts ran about 28.8 million exchanges between late April and early June to harvest Claude’s capabilities. Alibaba has not issued a detailed public rebuttal.
Is China’s GLM-5.2 as good as US AI models?
On coding and agentic benchmarks, GLM-5.2 sits within a few points of the top US systems, and independent security firms found it matching or beating them at finding software vulnerabilities. It still trails leading US models on broader general tasks. It is open-weight and costs a fraction as much to run, which is a large part of why it rattled US labs.
Can the US stop China from distilling its AI models?
Only partially. Anthropic wants tighter export controls and API restrictions, and senators are weighing sanctions on offending firms. But open-weight models like GLM-5.2 can be downloaded and run locally with no provider in the middle to block accounts, so once weights spread widely there is no choke point for an export order to reach.
The Business Model Analyst Take
Strip away the geopolitics and this is a story about a moat that is narrower than its owners assumed. US labs priced their businesses on the belief that a frontier model would stay proprietary and hard to copy for a long time. Distillation, open weights, and fast-following Chinese labs are all pushing in the same direction: capability is becoming a commodity faster than anyone wanted, and the premium for being six months ahead is shrinking.
That reframes what US labs are actually asking Congress for. The distillation letters read like an IP-theft complaint, but the underlying request is closer to moat insurance from the state, using export controls and sanctions to slow rivals that the market is no longer slowing on its own. It may be justified on national security grounds. As pure business strategy, leaning on regulation to defend a moat that technology is dissolving is a warning sign, not a plan.
The more durable position belongs to whoever wins the next layer. If the value is migrating from the raw model to agents, distribution, proprietary data, and the workflows customers actually run inside, then the lab that gets copied on benchmarks can still win on everything downstream. The uncomfortable takeaway for US labs is that GLM-5.2 did not just copy a score. It exposed how quickly the thing they were selling stops being scarce, and how little a crackdown can do about it. The companies that internalize that will spend less energy policing the copy and more building the part that cannot be distilled.